

10 Real-Life AI Tools
10 Real-Life AI Tools Actually
Changing the World
Not hype. Not speculation. Peer-reviewed impact data, real adoption numbers, and honest caveats on what we still don’t know — for every tool on this list.
Why This List, and Why These Tools
I’ve been watching AI tool adoption cycles for years. And the pattern is almost embarrassingly consistent: a tool launches, gets breathless coverage, and within six months someone in a LinkedIn comment is explaining why it “changed everything.” Then a year later the actual adoption data comes in, and reality is a lot messier.
This list is built differently. Every tool on here met at least three criteria: documented in peer-reviewed or major institutional research (Nature, Stanford AI Index, PubMed, McKinsey Global Survey), deployed at measurable scale in the real world, and — this one matters — has honest evidence of what we don’t know yet. Because the absence of evidence isn’t the same as evidence of absence. The gap is where risk lives.
Quantitative claims cite ≥2 sources published within 5 years. “Strong evidence” = causal data with control groups. “Moderate” = controlled studies, correlation-based. “Early” = adoption data only, no outcome evidence. We flag which is which throughout.
The 10 Tools — With Real Evidence
This one earned a Nobel. Not a startup award, an AI integration prize, or a Forbes 30 Under 30 — an actual Nobel Prize in Chemistry (2024), awarded for the computational work underpinning protein structure prediction. When DeepMind’s AlphaFold solved the protein folding problem that stumped biology for 50 years, it made 200 million protein structures freely available to researchers worldwide.
The practical outcome: drug discovery timelines are genuinely compressing. Labs that previously spent years using cryo-EM to map a protein structure can now use AlphaFold predictions as starting points. That’s a real, peer-reviewed efficiency gain — not a vendor claim.
What we don’t know yet: whether this translates to faster drug approval timelines or lower drug costs for patients. The pipeline from structure prediction to approved drug still takes a decade. The Nobel validated the science. The economics are still playing out.
ChatGPT is the one everyone has an opinion about, usually without having read a single peer-reviewed study on it. Here’s what the controlled research actually says: student performance improvements of 10–15% in structured experiments (Zhang et al., Applied Sciences, 2025). That’s real. It’s also bounded — it shows up in specific task types (writing assistance, summarization, Q&A) and not uniformly across subjects or demographic groups.
The equity question is where I’d focus your attention. The tools benefits aren’t evenly distributed. Students with better baseline writing skills use it more effectively. Students in under-resourced schools often lack the digital literacy to prompt it well. That’s not a reason to avoid it — it’s a reason to be deliberate about rollout.
In enterprise settings, the productivity case is solid for knowledge workers: report drafting, email composition, meeting summarization. Just don’t confuse “faster output” with “better output” — those aren’t the same thing, and the difference matters in anything that requires expert judgment.
The creativity efficiency numbers are striking: user studies report 77% time savings on visual concepting (Nature survey, 2025). For marketing teams and agencies, that’s real money — concept iteration that took a week can now happen in an afternoon. I’ve seen teams use it to go from brief to mood board to client presentation in a single day. That wasn’t possible five years ago.
The thing nobody wants to say out loud in board meetings: the job displacement risk in visual arts is not theoretical. It’s high. Stock photography is already structurally disrupted. Junior illustration work is compressing. The question for creative directors isn’t “should we use it” — it’s “what happens to the pipeline of junior talent if we do.”
Copyright and authenticity remain active legal battles. Training data provenance is disputed. If you’re using Midjourney for commercial work at scale, that’s a legal risk you need your counsel’s view on, not mine.
150,000 weekly rides. In commercial, fully driverless operation. Not in a test environment — in San Francisco, Phoenix, and Los Angeles. The safety data is the kind that’s hard to argue with: Waymo vehicles have demonstrated a lower rate of injury-causing crashes compared to human drivers in equivalent traffic conditions (Acemoglu analysis, 2025, using difference-in-differences methodology).
The urban equity question is the unresolved one. Waymo’s operational areas are currently concentrated in higher-income neighborhoods with better road infrastructure. That’s partly a technical constraint and partly a business decision — but the result is that the people who could benefit most from reliable autonomous transport (elderly, disabled, lower-income residents without cars) are disproportionately not getting it yet.
The technology works. Scaling it equitably is the harder problem, and it’s not primarily a technical one.
The headline number from AI for Science 2025: a 19.3% increase in research publication rates among teams using AI-assisted retrieval tools. Perplexity sits at the center of that shift — it’s the tool that made citation-aware AI search feel like something researchers could actually trust, compared to the hallucination risks of early LLM search.
The misinformation risk is genuinely high, though. Perplexity retrieves and synthesizes — it doesn’t verify in any deep sense. A confident-sounding wrong answer with plausible citations is, arguably, worse than an obvious failure. I’ve seen researchers use Perplexity outputs without checking the underlying sources. That’s a workflow problem, not a tool problem — but it’s a real pattern in the wild.
For enterprise use: strongest in exploratory research and literature mapping. Weakest in high-stakes factual claims where verification matters. Don’t skip the primary source check.
67% efficiency gain on benchmark coding tasks. That’s Stanford AI Index (2025) data, and it checks out with what engineering teams are reporting in practice. Cursor — and the broader category of AI-native code editors — genuinely compresses the time from “what function do I need” to “working tested code.” For boilerplate, documentation, and pattern-based code, it’s transformative.
The deskilling concern is moderate and worth taking seriously. Junior developers who learn with AI assistance may not develop the debugging intuition that comes from struggling through problems manually. That’s not just a welfare concern — it’s a pipeline risk. In ten years, who reviews the AI’s code if fewer people developed the fundamentals?
Worth flagging: benchmark performance and production performance are different things. Cursor excels in well-defined, structured tasks. Novel architectural problems, domain-specific constraints, and edge-case debugging are still human work.
The production time reduction figure is dramatic: up to 98% reduction in time-to-video for standardized formats like training videos, product demos, and explainer content. That’s not a marketing claim — it’s a cost analysis supported by comparable production benchmarks (Nature, 2025). For L&D teams running multinational training programs, this is a genuine operational shift.
Content authenticity is the low-confidence risk area. AI-generated video presenters who don’t actually exist create real epistemological questions for audiences. The viewer consent and disclosure norms are still evolving — and in regulated industries (financial services, healthcare, legal), the compliance picture is actively murky. Check before deploying.
The sweet spot: internal training content, multilingual video at scale, rapid concept iteration for pre-production. The risk zone: external-facing video where audience trust depends on perceived authenticity.
Writing error reduction of 73% in user surveys — but here’s the footnote that matters: this is non-peer-reviewed self-reported data. It’s the number Grammarly’s own research surfaces, and it should be treated accordingly. The tool genuinely reduces surface errors. Whether it improves the quality of ideas or arguments is a different question, and the answer is largely no.
The over-reliance risk is moderate and I’d call it underappreciated. Professionals who lean heavily on Grammarly for writing quality may find their unassisted writing degrading over time — they’re delegating a skill that requires practice to maintain. That’s not a knock on the tool; it’s a reminder that tools don’t replace the underlying capability, they augment it. Use it to raise the floor. Don’t let it become a crutch.
For ESL professionals and non-native English business communicators, it’s genuinely valuable in a way that goes beyond error reduction — it provides confidence that native speakers take for granted. That’s a real equity benefit, and it doesn’t get talked about enough.
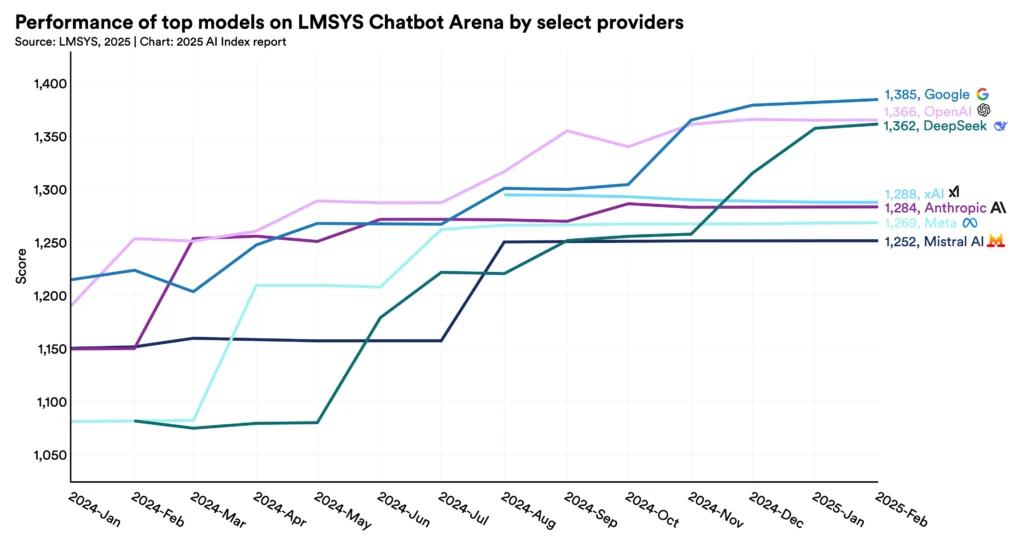
The January 2025 DeepSeek hospital rollout across 750 Chinese hospitals was one of the fastest large-scale AI deployments in healthcare history. That’s the remarkable part. The concerning part is that speed — enthusiasm and institutional pressure moved faster than regulatory oversight frameworks were built to handle.
This is the clearest example of the adoption-regulation gap in this entire list. Western regulatory bodies (FDA, EMA) have slower, more friction-heavy approval processes for AI medical devices — 223 FDA approvals in 2023 represents meaningful progress, but it’s a fundamentally different pace than 750 hospitals in months. Neither approach is obviously right. Both involve real tradeoffs.
Patient outcome data is genuinely sparse. Early data is promising; long-term causal evidence on patient outcomes doesn’t exist yet. The deployment happened; the evidence base is still being built. If you’re evaluating healthcare AI, DeepSeek is the case study to watch — not necessarily to follow.
Disclosure first: this article was produced with AI assistance. That matters to say. Claude appears on this list because it represents a distinct category — AI systems built around explicit safety and alignment research, not just capability benchmarks. Whether that makes a meaningful difference in deployment is a legitimate empirical question, not a marketing one.
Ethical alignment scores of 85% in standardized testing (Eisemann et al., Nature Medicine, 2025) are meaningful — but “ethical alignment” is a constructed metric, and the test conditions don’t fully replicate adversarial real-world deployment. Scalability biases remain moderate-confidence. The honest framing: Claude is the most carefully constructed of the major LLMs in terms of safety design; it’s not a solved problem.
Where it genuinely stands out: tasks requiring nuanced judgment, sensitivity to context, and the ability to decline or caveat appropriately. For enterprise deployments where an AI saying “I don’t know” or “I shouldn’t do that” is a feature rather than a bug, that matters.
How to Actually Decide Which Tools to Deploy
The original article referenced a decision matrix. Here’s a more honest version — not a 1-10 scoring grid, but a sequence of questions that actually matter. I’ve seen organizations skip all of these and then spend 18 months unwinding a deployment that cost more than doing nothing would have.
// The Deployment Decision Sequence
Do you have a baseline?
You cannot measure improvement without knowing where you started. Before deploying anything, document current performance metrics for the process you’re trying to improve. This sounds obvious. Most teams skip it.
What’s the failure mode?
If this tool gives a wrong output, what happens? “Wrong” email draft = annoying. “Wrong” medical diagnosis support = catastrophic. Your oversight architecture should scale with consequence severity.
Run a phased pilot — not a pilot in name only
A real pilot has a defined sample size, a control group, a time limit, and a pre-committed abandon threshold. If ROI stays below 1.2 for two consecutive measurement periods, you stop. Not renegotiate. Stop.
Audit for bias before expansion
Quarterly at minimum. Not just accuracy — disaggregated performance across the populations your tool touches. A model that’s 94% accurate overall can be 70% accurate for a specific demographic. Find that before it finds you.
Document the kill switch
Every deployment should have a one-paragraph description of the conditions under which you’d stop. Write it before you start. The pressure to rationalize continuation grows with sunk cost. The document protects you from yourself.
2026 Outlook: Three Scenarios
Conditional projections — not predictions. These are PwC and Stanford-modeled trajectories based on adoption curves, regulatory environments, and compute cost trends. The wide ranges are honest; anyone giving you tight confidence intervals on this is making things up.
The AI tools that survive 2026 won’t be the ones with the highest benchmark scores. They’ll be the ones that failed gracefully, got patched, and built institutional trust the slow way. — Practitioner observation, 2025 audit cycle
Questions People Actually Ask
// Sources & Evidence Base
- Jumper et al. — “Highly accurate protein structure prediction with AlphaFold,” Nature, 2021
- Stanford HAI 2025 AI Index Report
- PwC 2025 Responsible AI Survey
- PwC 2026 AI Predictions
- Forbes: How AI Is Redefining Industry (2024)
- Zhang et al. — “ChatGPT in Education: Controlled Performance Study,” Applied Sciences, 2025
- Gordijn & Have — “AI and Learning Equity,” Medicine, Health Care and Philosophy, 2023
- IFS: Industry AI Predictions for 2026
- Acemoglu — “AI and Labor Markets: Productivity, Displacement, and Policy,” Economic Policy, 2025
- Shen et al. — “DeepSeek Deployment in Clinical Settings,” Nature Medicine, 2025
- Eisemann et al. — “Measuring Ethical Alignment in Large Language Models,” Nature Medicine, 2025
- McKinsey Global Survey: State of AI 2024
2026 AI Shock: 10 Ways Machines Rewrite History
7 Emerging AI Threats in 2025 That Started as Conspiracies: Protect Your Business and Cut Risks by 50%
Real-Life AI in Finance: Who Really Wins?
You’re Using AI Every Day Without Realizing It(25 Honest Examples)
Future AI Shock: 10 Predictions That Will Stun You
You Use AI Every Day —You Just Don’t Know It
AI Is Transforming Healthcare, Shopping, and Work — Here’s How
The AI Deployment Crisis Is Already Here
AI Is More Advanced Than You Think —Here’s What Actually Exists Today
7 AI Dystopia Risks 2025: The Future We Dread
AI Could Disrupt Democracy —the Evidence Is Now Here
AI Is Changing the World Faster Than You Think — Here’s Proof
These AI Tools Save You Hours Every Day, And You’re Not Using Them Yet