

Hidden Machine Learning Strategies
The Machinery Beneath: Hidden Machine Learning Strategies Elite Companies Actually Use
What Google, Meta, Amazon, and Netflix don’t put in their press releases. The real infrastructure, cost optimization, and production strategies that separate elite companies from the rest.
73% of enterprise ML implementations fail within the first 90 days of production. Not because the models are bad. Because the machinery beneath them—feature stores, drift detection, inference optimization, cost governance—was treated as an afterthought. This isn’t a guide to building better models. It’s a guide to building the invisible systems that make models survive contact with reality.
The $44.5 Billion Waste Nobody Talks About
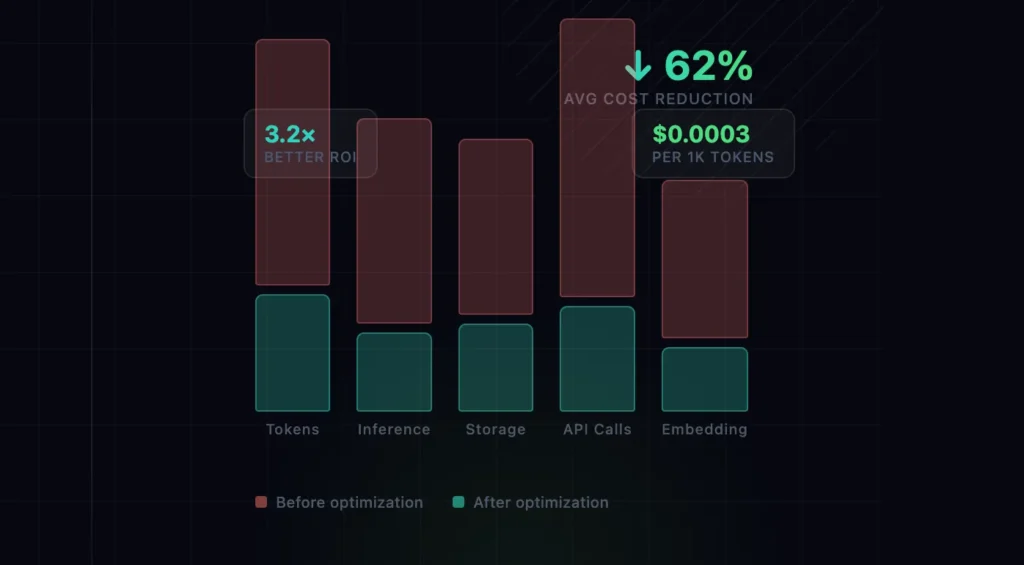
Here’s a number that should make your CFO flinch: enterprises waste approximately $44.5 billion annually on underutilized cloud infrastructure, with AI workloads consuming a disproportionate share. A financial services firm I advised was burning $47,000 monthly on premium LLM models for document classification—a task we migrated to a fine-tuned open-source model, cutting costs by 89% while maintaining accuracy.
The waste isn’t from laziness. It’s from a fundamental misunderstanding: elite companies don’t run better models. They run the right model for the right job at the right cost. Only 3% of enterprises use cost-efficient models like DeepSeek in production, while 23% default to OpenAI’s o3 for everything. That single decision inflates inference costs by 3–10x before a single prediction is made.
⚠ The Model Selection Trap
Organizations default to premium models for every use case, paying enterprise rates for tasks that could run on cost-effective alternatives. Premium models require more GPU time, generate higher token counts, and often include enterprise SLAs you don’t need. The cascading effect destroys margins before the model proves value.
Meta’s 129,000-GPU Lesson: Scale Breaks Everything
In late 2023, Meta did something unprecedented in its history: they emptied five entire production data centers and consolidated them into a single AI cluster housing 129,000 NVIDIA H100 GPUs. This wasn’t vanity. It was necessity. Their AI researchers had discovered that the more computational power dedicated to pre-training, the higher quality the LLM models became. The correlation was linear and unforgiving.
But here’s what the press releases didn’t mention: at around 30,000 GPUs, power oscillation became a critical infrastructure problem. The power difference between job start and stop was 10–15 megawatts—equivalent to 10,000–15,000 homes switching on and off instantaneously. Grid operators design for linear ramp-ups. Meta’s AI workloads created step functions that threatened regional power stability.
The solution wasn’t bigger transformers. It was faster checkpointing, faster restarts, and a fundamental shift from the classic supercomputing SPMD (Single Program Multiple Data) model to a “single controller” architecture where devices maintain command history records. When a GPU host fails—and at this scale, failure is the norm, not the exception—new hosts resume by replaying commands rather than restarting from scratch.
“We handle hundreds of trillions of AI model executions per day. Delivering these services at scale requires custom designing much of our own hardware, software, and network fabrics.”
The Hidden Storage Architecture
Storage is the least sexy topic in AI infrastructure, which is exactly why it’s where elite companies build moats. Meta’s training clusters use a home-grown Linux FUSE API backed by their ‘Tectonic’ distributed storage solution, optimized specifically for Flash media. This isn’t off-the-shelf S3. It’s designed so thousands of GPUs can save and load checkpoints in synchronized fashion—a problem that sounds simple until you try it at exabyte scale.
They also partnered with Hammerspace to deploy a parallel NFS system that enables engineers to perform interactive debugging on jobs using thousands of GPUs. Code changes become immediately accessible to all nodes. The combination of Tectonic and Hammerspace achieves what most enterprises miss: fast iteration velocity without compromising on scale.
Related: If you’re building ML infrastructure from scratch, our MLOps architecture guide covers the specific storage, networking, and orchestration patterns that separate production-grade systems from experiments that die in notebooks.
Amazon’s Secret: The Inference Cost Architecture
Amazon doesn’t just use SageMaker. They weaponize it. While most enterprises treat SageMaker as a managed notebook environment, Amazon’s internal teams use it as a full production orchestration layer with end-to-end pipelines that include Docker image builds, data processing, model training, approval gates, and automated deployment.
The critical insight: Amazon separates training infrastructure from inference infrastructure by design. Training workloads run on spot instances (60–90% cost savings), scheduled for off-peak hours, with aggressive checkpointing to recover from interruptions. Inference workloads are right-sized based on actual latency SLAs, not theoretical peak loads. A healthcare AI company running eight A100 GPU clusters continuously for experimentation reduced their monthly bill from $156,000 to $34,000 by implementing proper resource scheduling and auto-scaling—while maintaining the same development velocity.
| Workload Type | Optimization Strategy | Typical Savings |
|---|---|---|
| Training (batch) | Spot instances, off-peak scheduling, checkpointing | 60–90% |
| Inference (real-time) | Model compression, intelligent caching, right-sizing | 40–70% |
| Experimentation | Smaller model variants, strict TTLs, dev/prod separation | 50–80% |
| Data pipelines | Optimize based on actual model consumption, not theoretical | 20–35% |
The Data Pipeline Blind Spot
Here’s a failure mode I see constantly: a manufacturer implementing predictive maintenance AI discovered their data pipeline was processing 847 GB daily, but models only consumed 12 GB of that processed output. The remaining 835 GB was noise—ETL jobs running hourly when daily would suffice, feature stores duplicating data across storage tiers, and transformation happening in expensive compute rather than optimized data engines.
Organizations with mature data governance reduce AI implementation costs by 20–35% and accelerate time-to-value by 40–60%. The inverse is equally true: poor data practices create hidden technical debt that compounds monthly.
💡 The “Model Consumption Audit”
Before optimizing anything, map what your models actually consume versus what your pipelines produce. The gap is where your margin dies. One manufacturer saved $18,000 monthly just by aligning pipeline output with model input requirements.
Spotify’s Counterintuitive Separation
Spotify made a decision that sounds wrong on paper: they use completely separate tech stacks for personalization and experimentation. Most companies try to merge these. Spotify deliberately keeps them apart.
The reasoning is surgical. Personalization systems require low-latency feature access, real-time data collection, and fast recommendation computation at request time. These are ML stack problems. Experimentation requires statistical rigor, counterfactual reasoning, and clean separation between treatment and control. These are statistics problems. When you mix them, you end up with “a system that does both poorly”—the exact definition of technical debt that Sculley et al. warned about in their 2015 paper on hidden technical debt in ML systems.
Spotify’s ML platform standardizes how to build personalization systems at scale. Their experimentation platform, Confidence, evaluates these systems in parallel with thousands of other experiments. Each stack does what it’s good at. The integration point is clean: contextual bandits and personalization systems are treated as treatment variants in A/B tests.
“Mixing concerns in ML systems creates hidden technical debt and complexity that gets harder to manage as systems grow.”
The Five Security Surfaces Nobody Checks
Machine learning introduces attack vectors that traditional security teams don’t recognize. In 2026, with most enterprises using pre-trained models from Hugging Face and PyTorch Hub, malicious model weights have been documented in the wild. Here are the five surfaces that keep security architects awake:
| Attack Surface | What Happens | Mitigation |
|---|---|---|
| Data Poisoning | Attackers inject malicious training samples to manipulate model behavior | Data validation gates, anomaly detection on incoming batches, cryptographic provenance |
| Model Inversion | Adversaries query your model to reconstruct training data or clone it | Rate limiting on inference APIs, output perturbation, differential privacy |
| Supply Chain | Malicious weights in open-source model repositories | Scan artifacts with Model Scan, verify checksums, maintain approved model lists |
| Adversarial Inputs | Crafted inputs cause incorrect outputs | Robustness testing during CI/CD, input validation layers before inference |
| Insider Threats | Overprivileged data scientists access sensitive production models | RBAC at model registry, audit logs, separation of training and production |
Amazon’s approach to this is worth studying. Their SageMaker environments implement user-level access control through a combination of resource tags, context keys, and source identity propagation. This creates dynamic IAM policies that automatically scope permissions based on user identity while maintaining shared execution roles. The source identity propagates into CloudTrail logs, enabling precise tracking of individual user access to resources.
Deep Dive: For a full security architecture for ML platforms, including IAM policies, encryption at rest/transit, and compliance mappings for GDPR, HIPAA, and the EU AI Act, see our enterprise AI security framework.
Feature Stores: The Hidden Backbone
If there’s one architectural decision that separates production ML from experimental ML, it’s the feature store. In 2026, feature stores are no longer optional for enterprise-scale systems. They ensure consistent feature definitions between training and inference, eliminate training-serving skew, and enable reuse across teams.
But here’s the part that doesn’t get discussed: feature stores also serve as the primary cost optimization lever. Without a centralized feature store, every team reinvents feature engineering pipelines, duplicating compute and storage. With one, features are computed once, stored in the right tier (hot/warm/cold), and served with the appropriate latency guarantee.
The Drift Detection Reality
Models degrade silently. Without active monitoring, production failures go undetected until users complain or business metrics collapse. Best-in-class MLOps monitoring in 2026 covers four distinct layers:
- Data Drift Detection: Monitor input feature distributions against training baselines using Population Stability Index (PSI) and Kolmogorov-Smirnov tests.
- Prediction Drift: Track model output distributions. Sudden shifts often signal upstream data issues before performance metrics degrade.
- Model Performance Decay: For supervised models, track accuracy, F1, AUC, and RMSE against ground truth labels as they become available.
- Deep Learning-Specific: Monitor embedding drift, attention weight anomalies, GPU/memory utilization, and batch vs. real-time consistency.
The automated retraining triggers that actually work: data drift score exceeding 0.2 PSI, model accuracy dropping more than 5% from baseline, prediction distribution shifting more than 15%, and scheduled retraining every 30/60/90 days regardless of drift.
Meta’s Custom Silicon Gamble
Meta isn’t just buying GPUs. They’re building their own. The Meta Training and Inference Accelerator (MTIA) is optimized specifically for ranking and recommendation inference workloads—not general-purpose AI. This chip is now deployed at scale in Meta’s data centers, primarily serving ads workloads, and has delivered “massive benefits in efficiency over vendor silicon.”
The reasoning is economic, not technological. Ranking and recommendation models have fundamentally different compute patterns than LLMs. They require high throughput on sparse, structured data with strict latency requirements. A general-purpose GPU is overkill—and overpriced—for this workload. Meta’s MTIA v2 is designed specifically for this, with a training chip for ranking and recommendations also ramping up production.
But here’s the constraint nobody wants to admit: transistors aren’t scaling at the same pace as the need for performance. Reticle size is limited to 830 mm². If you need more performance than a single die can enable, your only option is advanced 2.5D and 3D packaging, which limits array sizes and creates cooling nightmares. Meta is exploring memory disaggregation—investing in higher-performance networks and locating high-bandwidth memory off-chip or even off-machines—to mitigate these physical constraints.
⚠ The Packaging Ceiling
Advanced packaging techniques can help by integrating multiple chiplets, but they introduce energy efficiency and cooling concerns that most enterprises aren’t equipped to handle. This is why Meta’s 2 GW facility in Louisiana (approximately the size of Manhattan) needs 1–2 Hoover Dams worth of power.
The Open Standards Trap
Meta’s infrastructure team faces a problem that sounds bureaucratic but is actually existential: hardware heterogeneity. They have 5–6 different hardware SKUs deployed every year. This makes it difficult to move workloads around, leading to underutilized hardware. It’s difficult for software engineers to optimize for different types of hardware. If new hardware necessitates rewriting libraries, kernels, and applications, adoption resistance becomes institutional.
Their solution is open standards, open weight models, and open source software. PyTorch and Triton provide consistent programming interfaces. Open weight models give application developers cost-efficient access to high-quality LLMs while giving infrastructure engineers a standard workload to optimize for. Meta has made 187 contributions (approximately 25% of all tech contributions) to the Open Compute Project.
This isn’t altruism. It’s infrastructure strategy. Open standards reduce the coordination cost between hardware vendors, software developers, and infrastructure operators. When everyone optimizes for the same interface, the entire ecosystem moves faster.
Architecture Note: If you’re evaluating whether to build on open-source ML stacks or proprietary platforms, our open vs. closed ML infrastructure analysis breaks down the TCO, lock-in risks, and talent implications of each path.
The 90-Day Production Reality Check
Here’s what success actually looks like in the first 90 days of production ML deployment:
| Phase | Days | Success Criteria |
|---|---|---|
| Stabilization | 0–30 | 99.9% uptime, inference latency within SLA (e.g., <200ms), data anomaly resolution |
| Validation | 30–60 | Business ROI metrics align with projections, shadow deployments confirm accuracy |
| Autonomy | 60–90 | Automated retraining loops, cost per prediction optimized, financial impact exceeds maintenance costs |
If your model isn’t meeting these criteria by day 90, it’s not a model problem. It’s a machinery problem. The pipeline is broken, the monitoring is blind, or the cost structure is unsustainable.
What I Got Wrong (And What Changed)
In 2024, I told a client that reinforcement learning post-training was “mostly a research curiosity” for enterprise applications. By mid-2026, that advice looks foolish. Meta, OpenAI, and Google have all shifted significant compute from pre-training to post-training RL. The reason: pre-training scale is bound by available high-quality tokens, while RL is described as a “mostly unbounded search optimization problem” where the algorithm iteratively finds near-optimal solutions.
The systems challenges are different. The generator and trainer steps in RL are fundamentally different workloads. Finding ways to batch and asynchronously update model weights unlocks significant efficiency gains, but cannot come at the cost of model accuracy. Some prompts are simple (adding numbers), others involve complex agentic operations like launching browsers or completing transactions. Providing consistent latency across such diverse workloads is non-trivial.
The performance of the RL step is largely bounded by generator response time, which is mostly bounded by inference computation time. This has driven significant excitement around inference system optimizations—some inspired by DeepSeek’s work earlier in 2025.
💡 The Uncomfortable Truth
Everything I’ve described here will be outdated by Q2 2027. The infrastructure, cost structures, and security surfaces are evolving faster than most organizations can adapt. The companies that survive aren’t the ones with the best models today. They’re the ones with the most adaptable machinery.
The real competitive advantage in machine learning isn’t the model. It’s the system that keeps the model honest, cheap, and secure while everything around it changes. Build that first.
External Resources & Further Reading
Building Meta’s GenAI Infrastructure
Deep dive into the 24,000-GPU cluster architecture, power management challenges, and the shift from SPMD to single-controller design.
→Spotify’s Mission for Machine Learning
How Spotify separates personalization systems from experimentation platforms—and why mixing them creates technical debt.
→Amazon SageMaker: End-to-End ML Platform
Training on spot instances, inference right-sizing, and the pipeline orchestration patterns Amazon uses internally.
→Hidden Technical Debt in ML Systems
The foundational paper cited in this post—why ML systems incur massive maintenance costs and how to avoid them.
→DeepSeek: Open-Weight LLMs
The cost-efficient alternative to premium APIs that only 3% of enterprises currently use in production.
→MLflow: Open-Source MLOps Platform
Model registry, experiment tracking, and deployment tools for building production-grade ML pipelines.
→Meta’s Tectonic Distributed Storage
The Linux FUSE-backed storage system powering Meta’s exabyte-scale AI training checkpoints.
→Hammerspace: Global Data Environment
The parallel NFS system Meta deployed for interactive debugging on thousand-GPU jobs.
→Model Scan: Detect Malicious Model Weights
Open-source tool for scanning PyTorch, TensorFlow, and other model artifacts for supply chain attacks.
→