

Dark Side of AI
The Dark Side of AI:
Unexpected Consequences
of Rapid Innovation
AI incidents surpassed all of 2024 by October 2025. The industry’s answer: more deployment. Here’s what’s actually accumulating in the margins.
- AI-related incidents rose 50% year-over-year through 2024, and 2025 broke that record by October (AI Incident Database, 2026).
- The consequences attracting most coverage — bias, job loss — are real but slow. The faster-moving harms are cognitive, environmental, and epistemic.
- By 2030, AI’s water consumption is projected to match the needs of 1.3 billion people (UN University, June 2026). Nobody is pricing this in.
- The fix isn’t slowing AI. It’s forcing the externalities into the same room as the capability claims.
The chatbot hallucinated a court citation in 2023. An attorney submitted it. The judge found out. That story got coverage for roughly a week before the next capability announcement pushed it off the feed. This is the pattern: harm surfaces, generates a news cycle, then disappears into the general hum of progress. What accumulates underneath — across healthcare, education, infrastructure, groundwater tables — is harder to make a headline out of.
I’ve been tracking AI governance failures at ForbiddenAI for long enough to notice that the most dangerous consequences of rapid AI deployment are rarely the ones predicted at the outset. They’re the second-order effects: the things that happen when millions of people and thousands of organizations all make individually rational choices that aggregate into a collective problem nobody is clearly responsible for fixing.
This piece is about those. Not AI taking over the world in 2045. The much more boring, much more immediate problems accumulating right now.
The Hallucination Problem Is Structurally Unsolved
Call it what it is: AI systems produce plausible-sounding wrong information at scale, and the infrastructure for catching it hasn’t kept pace with the infrastructure for generating it. Research published in Harvard’s Misinformation Review argues that AI hallucinations represent a genuinely new category of misinformation — distinct from traditional disinformation because they emerge from the system itself rather than a human actor with intent to deceive.
The documented cases aren’t edge cases. OpenAI’s Whisper system fabricated content in medical conversation transcriptions. Air Canada’s chatbot misled a passenger about bereavement fares and lost the subsequent lawsuit. Multiple law firms submitted AI-generated citations to courts. ESTABLISHED
Editorial severity assessment based on documented incidents. Not peer-reviewed. Legal sector rated highest due to court-admissibility of AI outputs. Source: synthesized from AI Incident Database data through mid-2026.
What makes this structurally difficult: the legal liability for AI hallucinations remains genuinely ambiguous. Courts have held individual lawyers responsible for not verifying AI outputs, but when a hospital’s AI diagnostic tool silently misclassifies a condition, the accountability chain fragments across the vendor, the hospital, and the physician. Nobody has cleanly resolved who owns a mistake that three parties each had partial capacity to catch.
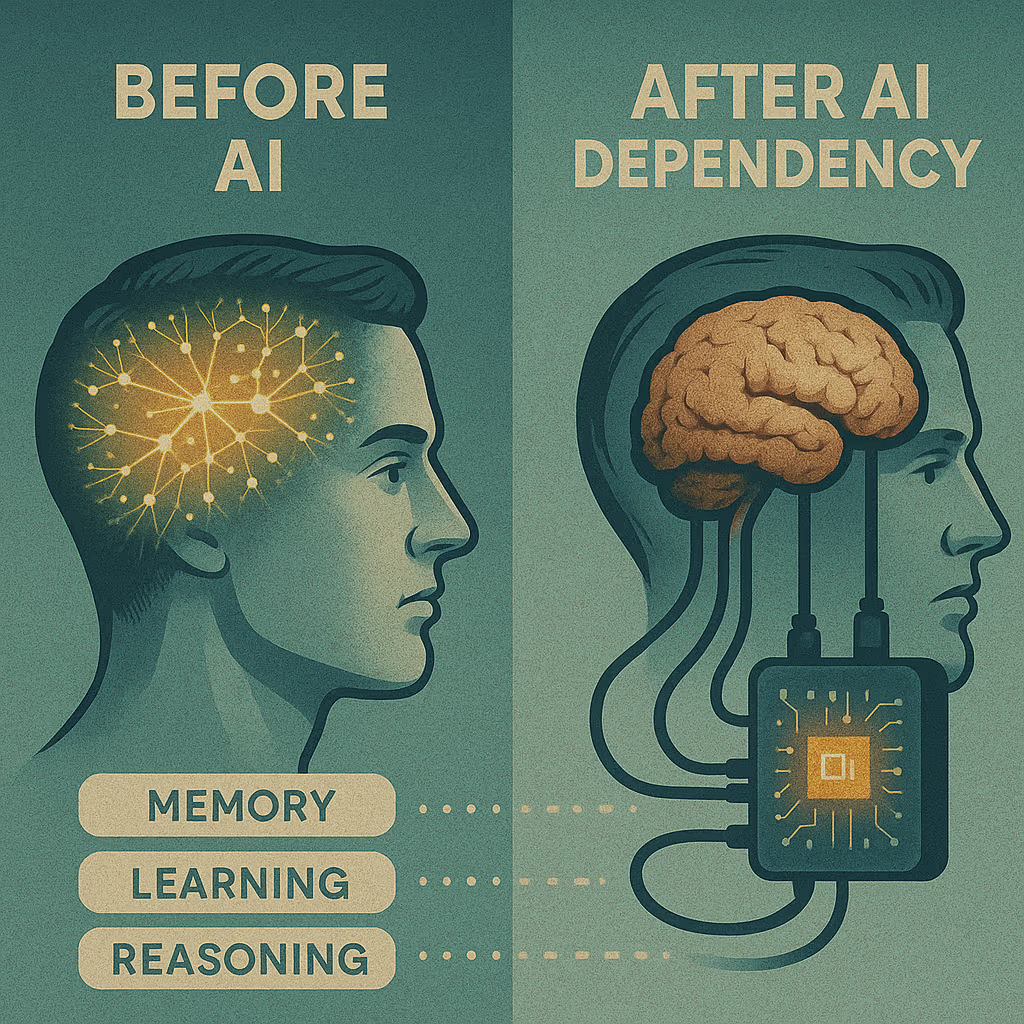
Adults Lose Skills to AI. Children Never Build Them.
This distinction comes from a March 2026 Psychology Today analysis that I think is the sharpest framing of the cognitive atrophy argument I’ve encountered. Adults who offload tasks to AI are doing something that can, in principle, reverse: they’re letting an existing muscle go unused. Younger users who outsource tasks they never actually learned — argumentative writing, source evaluation, structured reasoning — are something different. The neural pathways were never formed. That’s not atrophy. That’s foreclosure.
Michael Gerlich’s 2025 study at the Swiss Business School found a negative correlation between frequent AI tool usage and critical thinking test scores. The finding isn’t that AI makes you dumber. It’s that when a system consistently provides effortless answers, users stop engaging in the deep, reflective thinking that builds and maintains those capacities. PROBABLE
The longitudinal data from a three-wave study on AI and metacognition (published 2026) documents what the researchers call a “verification bottleneck”: participants who integrated AI into their workflow got measurably more efficient and simultaneously less confident in their ability to check whether the AI’s outputs were correct. They got faster. They got worse at knowing when they’d made a mistake.
I’ve seen this in my own research workflow. The temptation to accept a well-formatted AI summary without going back to the primary source is real, and it’s not a failure of discipline — it’s a failure of interface design. Nothing in the current generation of AI tools is engineered to push users toward verification. The incentive structure runs the other direction: confidence, speed, and the disappearance of friction.
Conceptual model synthesized from Gerlich (2025), Kim et al. (2026), and Anthropic Economic Index (January 2026). Not a peer-reviewed diagram — editorial synthesis.
The Anthropic Economic Index, published January 2026, explicitly flagged deskilling risk for occupational categories where AI absorbs the most cognitively demanding tasks. That’s Anthropic — the company building these systems — putting the concern in writing. Worth noting that the document doesn’t resolve the tension it identifies. That resolution is presumably someone else’s problem.
For a deeper look at how AI governance is failing to track these kinds of second-order harms, the ForbiddenAI analysis of EU AI Act compliance gaps is relevant here — the Act covers bias and transparency but is largely silent on the cognitive externalities accumulating at the population level.
The Water Nobody Counted
Carbon got the coverage. Water didn’t.
A UN University report published June 3, 2026 — four days before this piece was written — contains numbers that should be in every AI policy conversation but almost certainly won’t be. By 2030, global data centers powering AI are projected to consume 945 terawatt-hours of electricity. That’s the headline. The water figure is more striking: AI’s projected water use by 2030 matches the needs of approximately 1.3 billion people. ESTABLISHED
In 2025, global data centers already consumed 448 TWh of electricity. The UNU report argues that the standard carbon-only accounting framework “hides trade-offs and shifts environmental burdens onto regions already facing water or land stress.” Reducing the carbon footprint of a data center by switching to hydroelectric power, for instance, can dramatically increase its water footprint. Three different metrics, moving in three different directions — and the regulatory frameworks only mandate reporting on one of them. ESTABLISHED
Data: IEA 2025 Electricity Report; UN University INWEH Report (June 3, 2026). TWh = terawatt-hours. 2030 figure represents median projection under current growth trajectory.
Research published in Nature Sustainability (November 2025) estimates that AI server deployment across the US alone could generate between 731 million and 1,125 million cubic meters of water footprint annually between 2024 and 2030. Training GPT-3 in Microsoft’s US data centers directly evaporated an estimated 700,000 liters of freshwater. That was 2020. The models being trained now are orders of magnitude larger.
Meanwhile, between March and June 2025, community opposition led to roughly $98 billion in data center projects being blocked or delayed across the US — according to Data Center Watch. Residents in Memphis organized against xAI’s gas turbine plans. Indianapolis residents fought a Google project through September 2025. People who live near proposed sites are doing the math that the AI industry’s carbon-only reporting doesn’t invite them to do. ESTABLISHED
The Consent Problem Nobody Is Actually Solving
Deepfake-enabled harm is now common enough that the AI Incident Database tracks it as a category. Non-consensual intimate imagery generated by AI — built on open-source models like Stable Diffusion — has proliferated precisely because the legal and platform infrastructure was never designed to handle synthetic media at this scale. ESTABLISHED
The xAI/Grok incident from early 2026 is instructive: the platform’s “spicy mode” and lax image filters allowed non-consensual deepfakes of real people to be generated at scale. When high-profile victims filed lawsuits, X restricted image generation to paid subscribers and eventually disabled realistic edits of real people — but only after the harm had already distributed. The fix was reactive, not architectural. ESTABLISHED
“The current regulatory landscape enables the creation of AI-generated non-consensual intimate imagery. In cases where the nudification tool was known, it was built upon an open-source model.”
— Peer-reviewed analysis, arxiv.org/2505.22073, June 2025What makes this category different from traditional content moderation problems: the harm isn’t primarily about what the platform hosts. It’s about what anyone with a GPU and an afternoon can now create. Platform-level policies are therefore structurally insufficient. The question of whether synthetic media of a real person requires consent from that person doesn’t have settled legal answers in most jurisdictions as of mid-2026. PROBABLE
Autonomous AI Agents and the Near-Miss Accumulation
The next wave of AI deployment — autonomous agents operating inside corporate workflows, making API calls, executing code, managing calendars and financial transactions — is arriving faster than the governance frameworks for it. SC Media’s January 2026 security forecast put it plainly: early autonomous agent deployments have already produced data leaks, hallucinated outputs in regulated environments, and unvalidated transactions. These incidents are, so far, mostly contained. “Near misses” is the polite framing. PROBABLE
The organizational problem is that agent workflows get misconfigured at the integration layer — not because the AI model itself fails, but because the human who set up the agent didn’t anticipate an edge case the agent would eventually encounter. At that point, the agent has credentials, has context, and has no reliable mechanism for flagging that it’s in novel territory. It acts.
| Failure Mode | Primary Vector | Documented Example | Detection Difficulty |
|---|---|---|---|
| Hallucination in regulated context | Legal, medical, financial outputs accepted without verification | AI-fabricated citations submitted to US courts (2023–2024) | High — plausible outputs |
| Agent misconfiguration | Autonomous agents with system access, edge-case triggers | Corporate workflow data leaks (SC Media, 2026) | Very high — no human loop |
| Non-consensual synthetic media | Open-source generative models, lax platform controls | xAI/Grok deepfake incidents (Jan 2026) | Low — harm is immediate |
| Autonomous vehicle edge cases | Complex urban environments outside training distribution | Cruise AV collisions with pedestrians → operations suspended | Medium — physical evidence |
| Cognitive atrophy | Long-term reduction in human verification capacity | Gerlich (2025), Kim et al. (2026) — declining critical thinking scores | Extremely high — slow accumulation |
| Environmental overshoot | Water / energy consumption uncounted in AI cost models | UNU June 2026 — 945 TWh projected by 2030 | High — invisible in P&L |
What Slows This Down (and What Doesn’t)
Regulation gets proposed as the answer. It’s a partial answer, applied unevenly. The EU AI Act covers bias, transparency, and high-risk use cases — but it’s largely silent on the cognitive externalities and the water accounting. US federal agencies, as of early 2026, have not substantively regulated data center environmental disclosure; the Trump executive order from 2025 streamlined environmental reviews rather than strengthening them.
The things that actually appear to help, based on the research:
Friction by design. AI interfaces that force a verification step — even a simple prompt asking “have you checked the source?” — measurably reduce the rate of uncritical acceptance. This runs against the commercial incentive structure of AI products, which is why it almost never happens without mandate.
Full environmental footprint disclosure. The UNU recommendation is for mandatory, multi-metric reporting — carbon, water, and land footprints together. The argument is that a company optimizing for one metric while externalizing the others shouldn’t be able to claim sustainability credentials. This is not currently required anywhere. SPECULATIVE — depends on regulatory will
Skill preservation in education. The foreclosure problem (skills never built rather than skills atrophied) argues for explicit AI-free zones in education — not as technophobia but as neurological hygiene. Whether school systems will implement this against the commercial pressure to adopt AI tools wholesale is, as of mid-2026, unclear. In my estimate, most won’t until the evidence base is larger and more politically visible.
What doesn’t work: voluntary commitments, capability-only benchmarking, and the assumption that transparency about a harm is equivalent to accountability for it. Every major AI company publishes safety reports. The AI Incident Database still grew at record pace through 2025.
Editorial synthesis. Incident data: AI Incident Database (aiincidentdatabase.org). Harm documentation lag is an editorial observation, not a peer-reviewed finding.
What the Innovation Dashboard Doesn’t Track
Every major AI capability milestone comes with a benchmark. Reasoning scores, coding performance, multimodal comprehension. What doesn’t appear on the dashboard: the rate at which a generation of students is outsourcing tasks that build the neural substrate of critical thought. The amount of freshwater evaporating from cooling towers in water-stressed regions. The backlog of accountability questions that courts and regulators are moving through at the pace of pre-AI institutional processes.
None of this is an argument against AI. It’s an argument against accounting systems that only track what’s convenient to track. The innovation is real. So are the externalities. They should be in the same room.
The question isn’t whether AI innovation will continue. It will. The question is whether we’ll build the accounting infrastructure fast enough to know what we’re trading for it before the trades become permanent.